A short comment on how the Claude Code team does code review: what changes if everyone can see the conversation with the coding agent, not just the pull request it produced.
API keys, OAuth and JWT get listed side by side, but they aren't three alternatives: an API key is a credential, OAuth is a protocol for getting one, and a JWT is a format a token can take. Worked through on a support agent that has to call three systems.
A manufacturer that makes parts to its customers' drawings loses most of its quotes, and each one costs an expert hours. A system design that drafts the quote in minutes and leaves every decision to the expert.
A week-ahead forecast of hourly passengers per station, evaluated as it would run in production. Its lead over a calendar average that knows holidays came almost entirely from holidays, and the inputs SHAP ranked first made it worse.
German hospitals lose revenue on care that was documented but never coded. A system design to find it without upcoding: signals, evidence, a grouper and a coder.
Ball type predicted scrap, but the client knew that and couldn't change it. So we asked whether each sensor signal is independent of scrap given the ball type, answered it five ways, and, after correcting for testing twelve signals, found no evidence that any signal matters beyond the ball type. Why five methods, and what a null result like that still says.
Using Claude Design to iterate on the structure, wording and visuals of a hackathon case-study deck, with the full deck embedded.
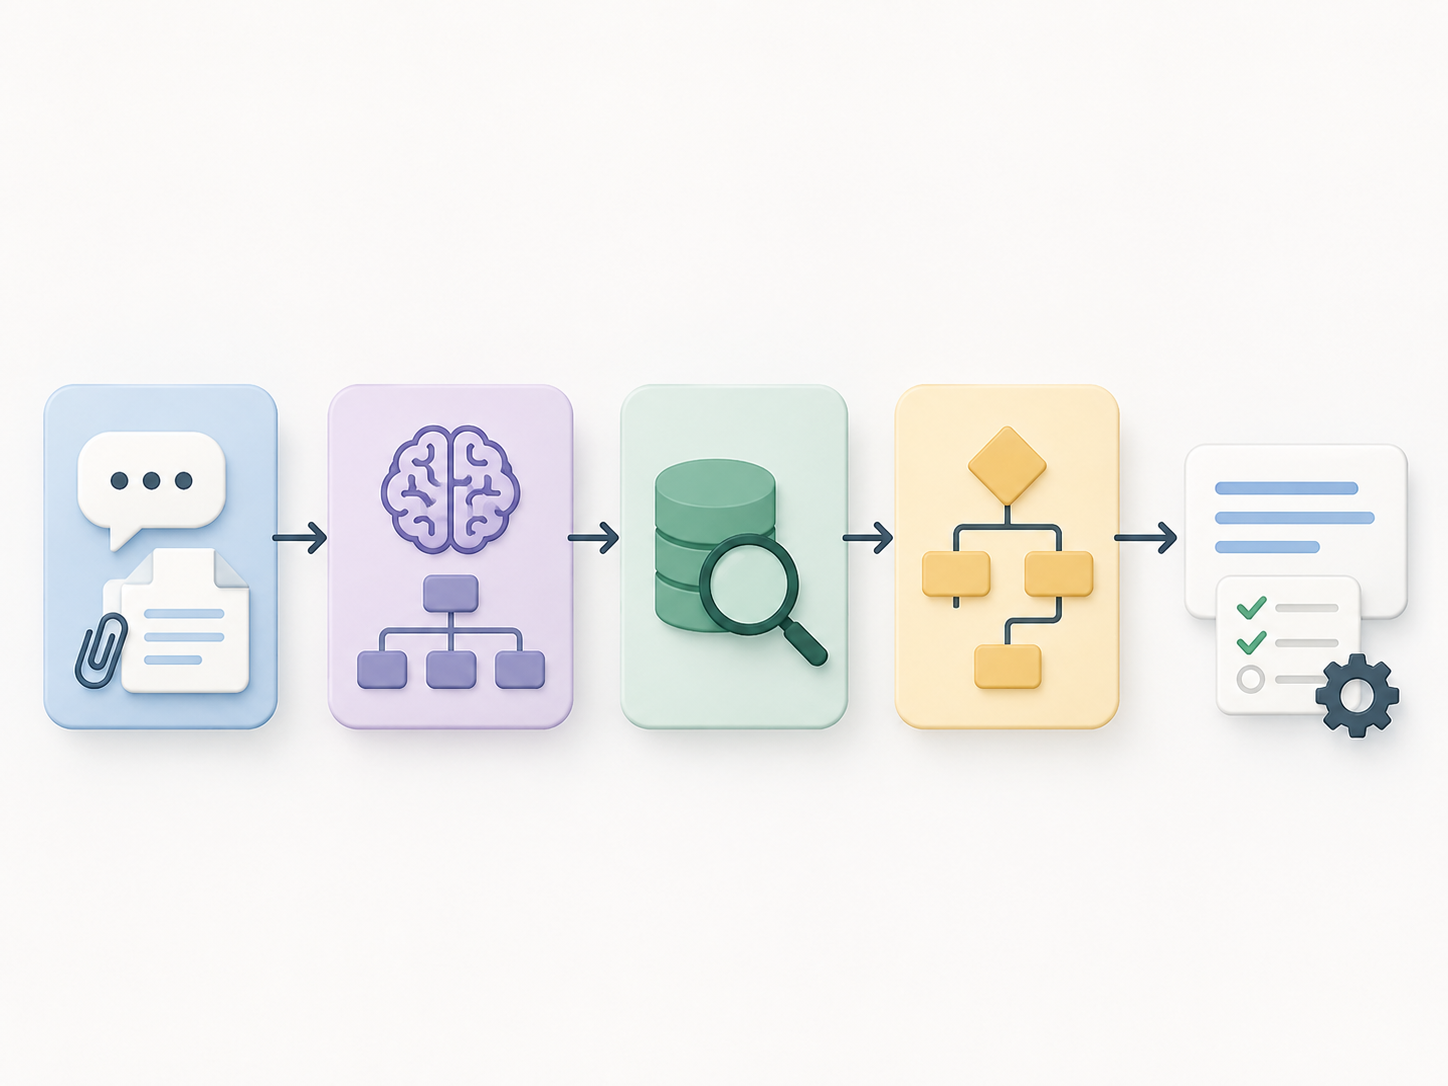
The four-step pipeline we landed on after iterating on live tickets: a rooted DAG of intents, grouped extraction, weighted-scoring fetch, and a mostly-hardcoded planner with an explicit LLM fallback.
Once agents write the code and AI reviewers iterate on it, a line-by-line diff is the wrong place to start a review. Start from the agent's transcript and decisions instead.
Causal masks, padding masks and cross-attention as small changes to self-attention: which positions may attend to which, and where queries, keys and values come from.
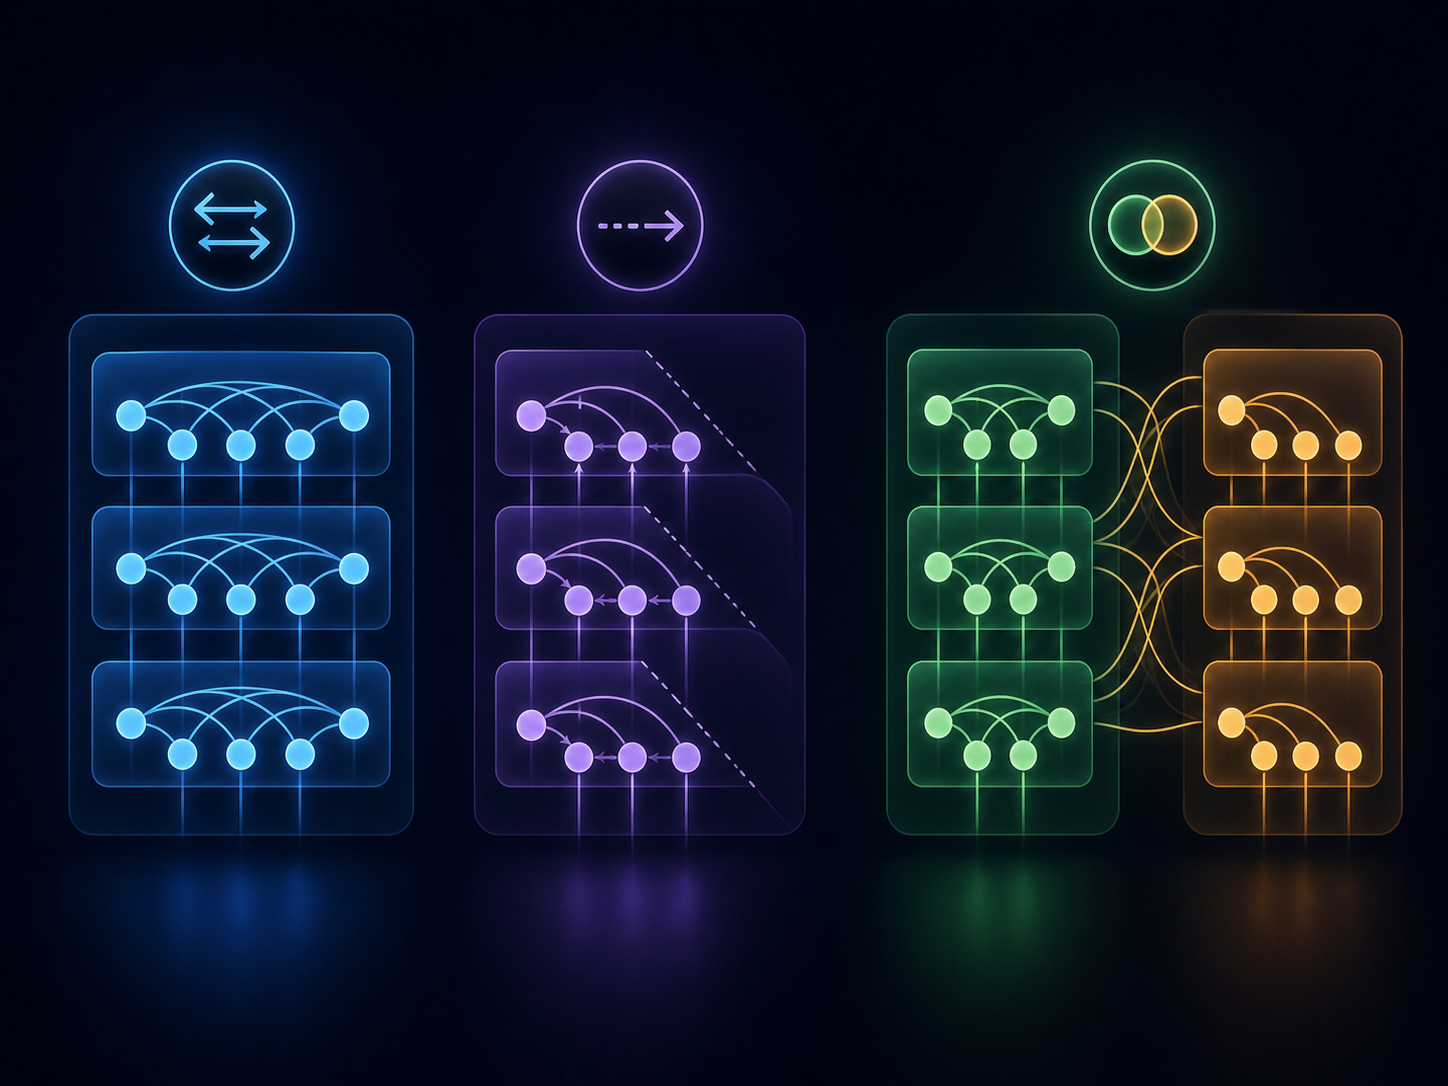
Self-attention is the mechanism. BERT, GPT, and T5 are three different ways to stack it.
A high approval rate on generated support replies is not a cost reduction. Why the two come apart, and the arithmetic worth doing before automating a support queue.
Deriving scaled dot-product self-attention from Nadaraya–Watson kernel regression step by step, in the notation of Murphy's Probabilistic Machine Learning.
Once coding agents make code cheap, business automation's bottleneck moves to the experts: with no test suite for a business process, only they can tell whether the output is right.
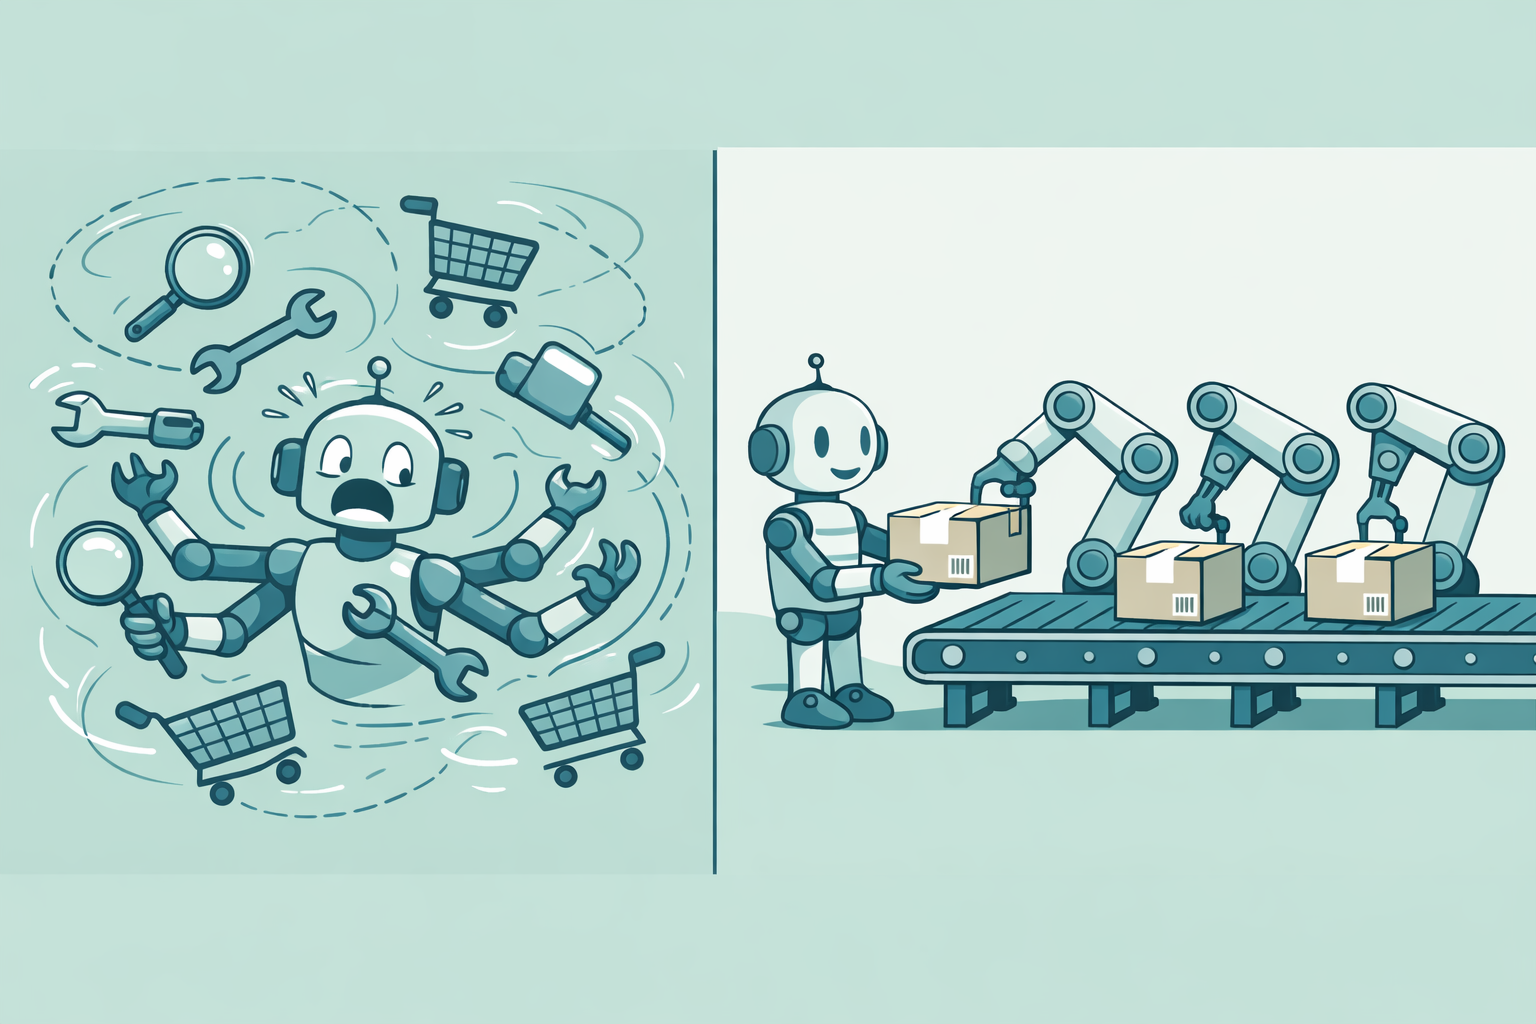
An agent holding every tool, or a workflow that keeps code in charge of the order of operations? Why I'd now make the agent the default, and move a request type into code only once it is common and the agent gets it wrong, or the action can't be undone.
A chapter-by-chapter verdict on Antonio Gullí's Agentic Design Patterns: which ideas hold up, which chapters to skip, and what has changed since publication.
How we tackled Challenge 2 at the Unite x TUM.ai Data Mining Hackathon: choosing which recurring purchases to recommend when each recommendation costs a fee, from raw procurement line items to a two-stage model, with industry-based picks for buyers who have no history.
Langfuse for monitoring and persisted eval runs, a Cursor-driven triage loop that turns failing traces into targeted fixes, and when to fix eval data rather than prompts.
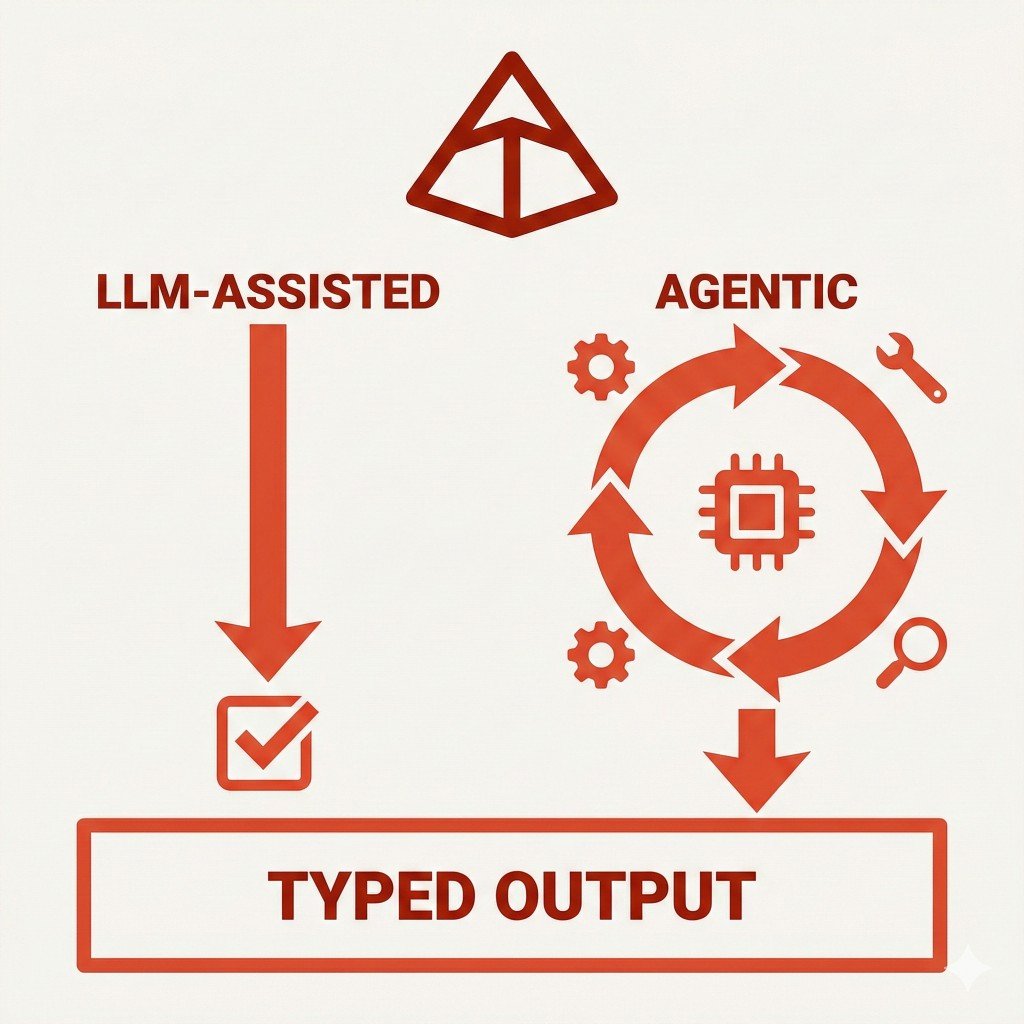
Pydantic models as the contract between deterministic, LLM-assisted and agentic steps, so moving a step from one to another is a local change.
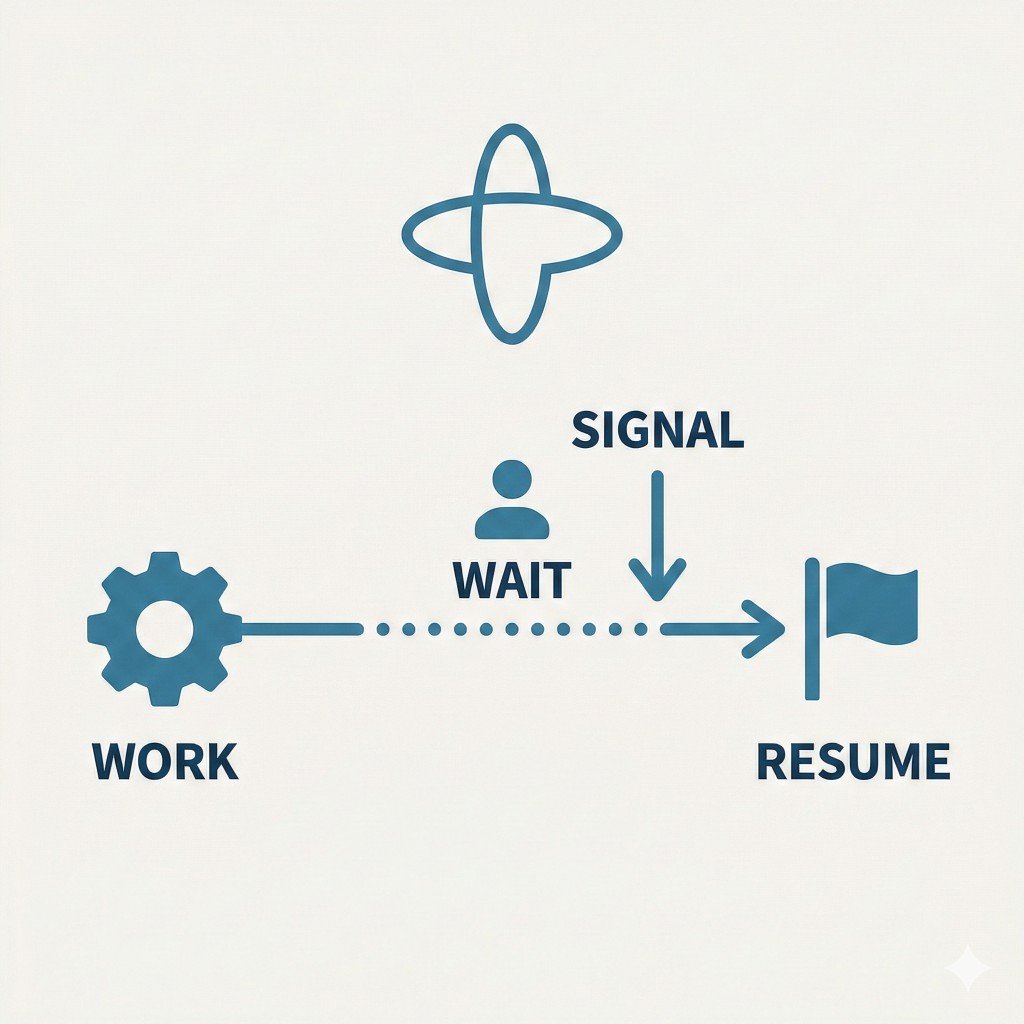
How Temporal's durable waits, signals, and deterministic recovery make human-in-the-loop workflows reliable when approval times are unknown.
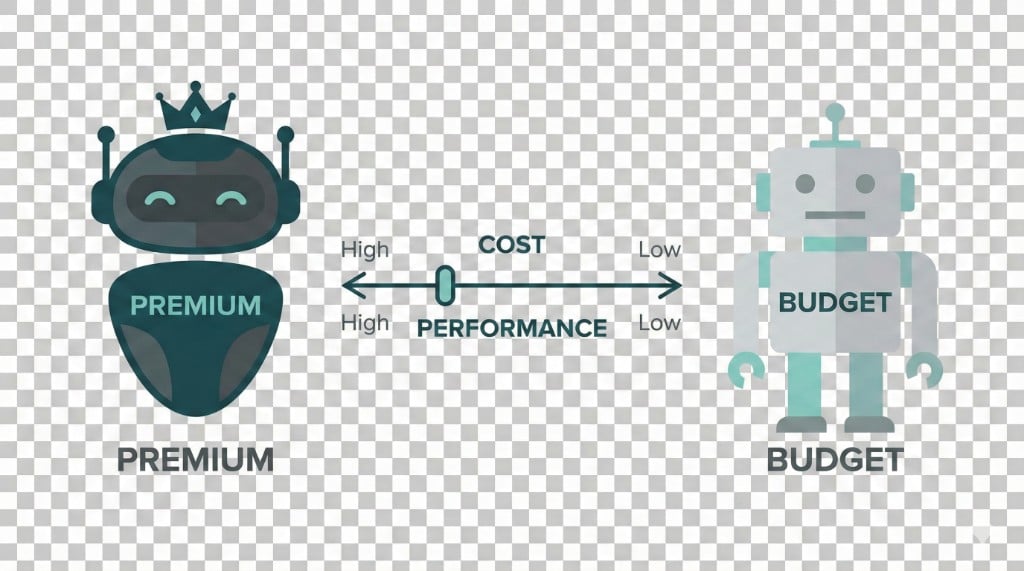
Use an expensive model for planning and a cheap one for execution in Cursor, with a cost-vs-performance chart built from Cursor's pricing and Arena scores.
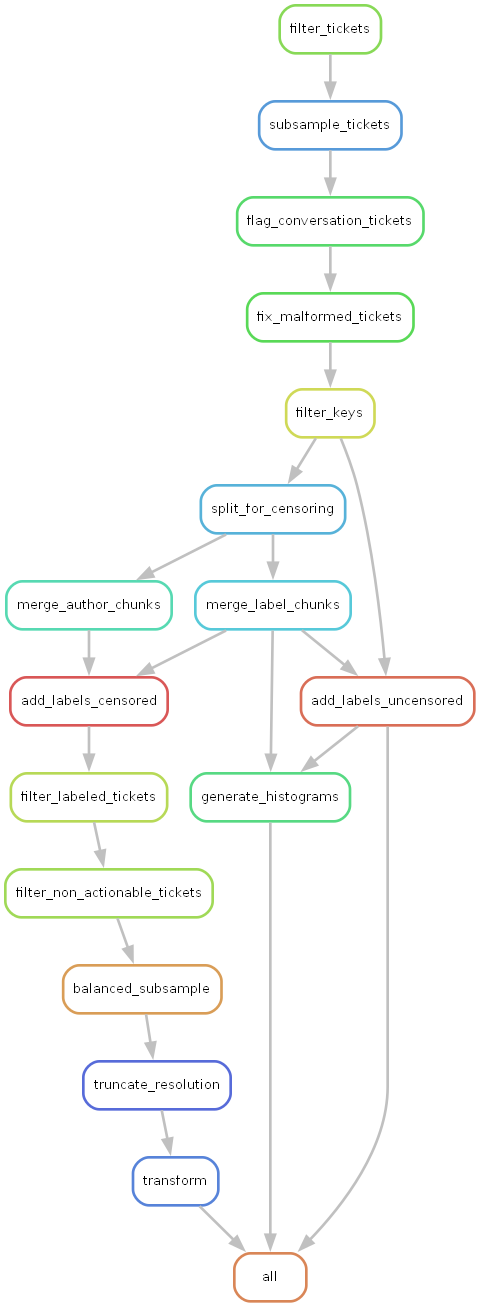
Scatter–gather and incremental reruns in Snakemake for an iterative LLM ticket-classification pipeline with 19+ stages, from PII censoring to training data.
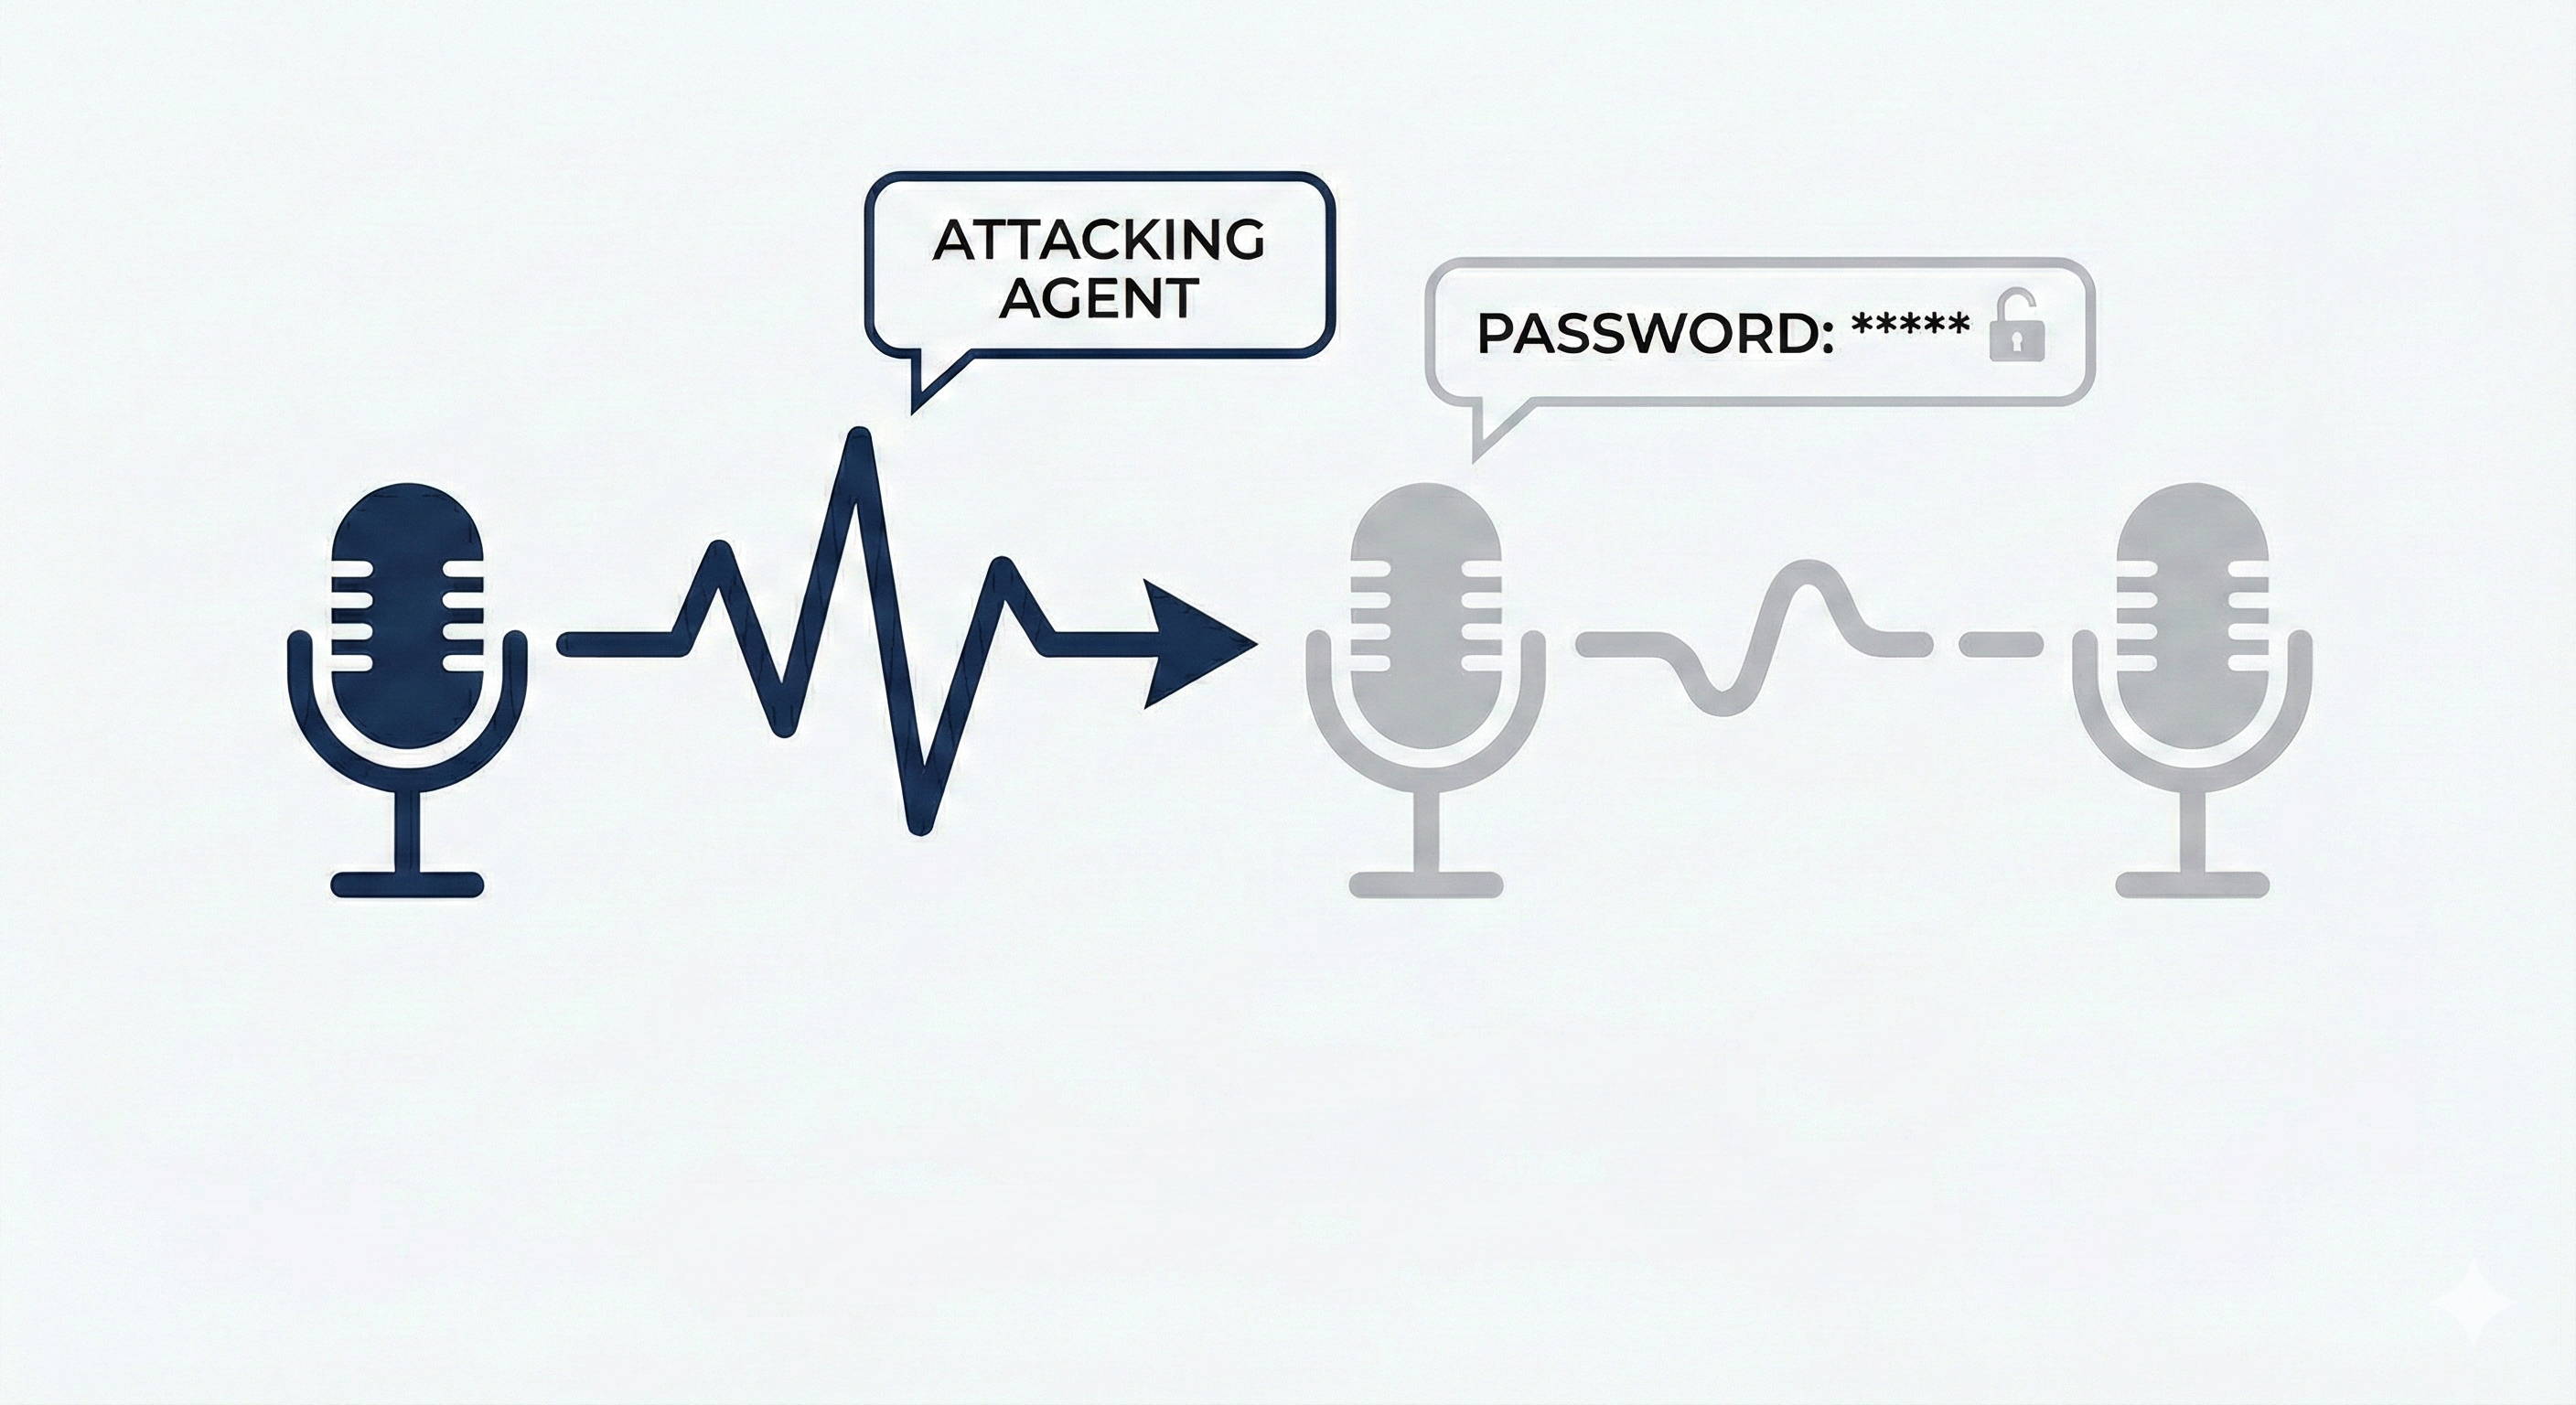
A white-hat prompt-injection challenge from the Agent Olympics Hackathon Munich 2026, and a live chatbot for you to try it on.
With DSPy you declare an LLM call's inputs and outputs in code, and the framework writes the prompt, parses the reply and can tune the prompt against a metric. A movie-review example, with and without it.
Links I come back to when building AI agents: frameworks, evaluation, observability and production engineering.
A deep dive into the technical implementation of my personal website, covering the AI chat interface, markdown context generation, and resume PDF sync from a dedicated CV repo.
An extension of the Hierarchical Dirichlet Process model that incorporates phylogenetic tree structures to capture evolutionary relationships in mutational signature activities.
A mathematically rigorous introduction to mutational signature estimation using Hierarchical Dirichlet Processes, deriving the steps that papers applying the model leave out.
A deep learning approach for diabetic retinopathy detection using fundus images, combining binary classification and image segmentation to identify disease presence and quantify key indicators.
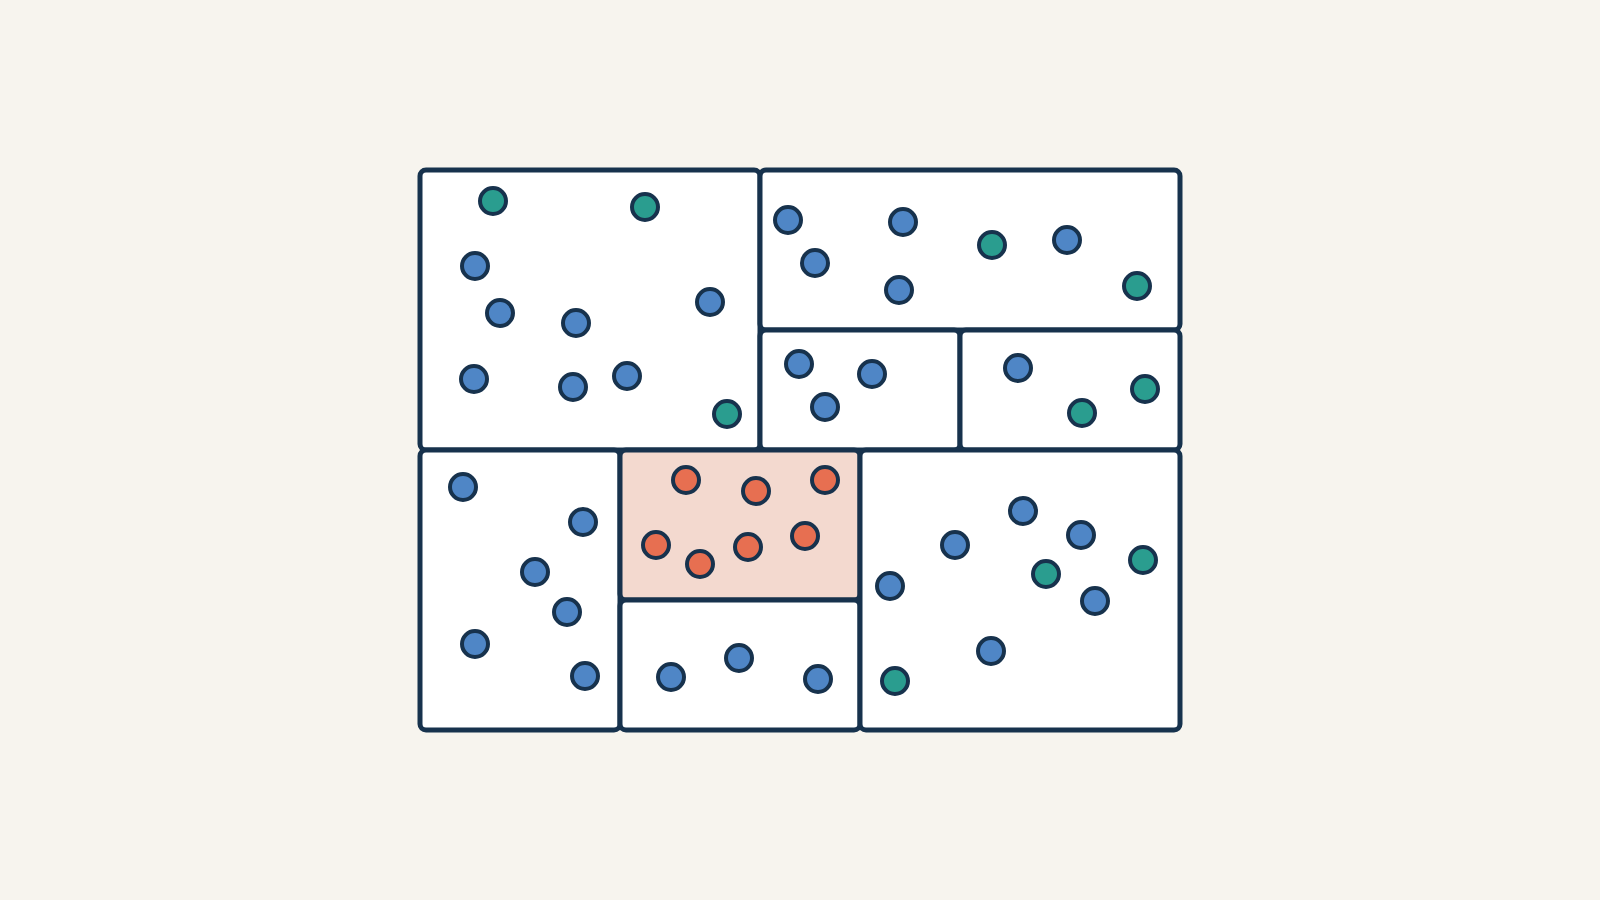
My master thesis implemented and tested IHW-Forest, an extension of the multiple testing method IHW from one covariate to many, proposed by Nikolaos Ignatiadis. What the method does, which parts were mine, and the full thesis embedded.
My bachelor thesis took a published paper on estimating the geometric median online and wrote out the steps its authors skipped, aiming to use only theorems from my lectures. What the paper is about, what that involved, and the thesis itself.
Messages you send are processed by the Google Gemini API to generate responses. Do not share sensitive personal data. See the privacy policy for details.